Flash Attention: Causal Prefill D=128
Updated September 2026. Target: NVIDIA H800 PCIe, SM90a, 114 SMs. BF16 inputs/output, FP32 accumulation, BSHD layout.
This worklog develops a causal prefill attention kernel with Croqtile. The current implementation goes beyond the original three-step demo: it uses operation futures, generation-aware events, a separate QK prologue and PV epilogue, and a persistent scheduling experiment. A newer non-persistent implementation makes the same compute pipeline easier to study.
The kernels and performance comparison on this page are distributed together as standalone ZIP and tar.gz downloads. The package includes generated CUDA and runtime headers, so running the demo requires CUDA and CUTLASS but does not require a compiler repository checkout. The comparison backends have their own Python dependencies, listed in the package README.
Workload and source map
The downloadable workload configuration defines the three measured shapes:
| Parameter | Value |
|---|---|
| Batch, query heads, KV heads | 4, 32, 32 |
| Query and KV sequence lengths | Both 4096, 8192, or 16384 |
| Head dimension | 128 |
| Mode | Causal full-sequence forward, without dropout |
| Layout and precision | [batch, sequence, head, dim], BF16 |
| Default timing | 50 warmups, 200 repeats |
The headline shape is B=4, H=32, S=8192, D=128. These are aligned prefill
cases, with equal Q/KV lengths and sequence lengths divisible by 128. The
optimized kernels below do not establish support for arbitrary tails, GQA,
unequal Q/KV lengths, or backward attention.
All kernel paths in this table are relative to the package's kernels/
directory. File numbers identify experiments, not a guaranteed speed ranking.
| Source | Role in the walkthrough |
|---|---|
| v1_manual_baseline.co | Sequential cooperative DMA, QK, softmax, PV |
| v2_manual_s2_1p2c_tma.co | One producer and two consumers, two-stage TMA pipeline |
| v4_nonpersistent_fa.co | Current teaching implementation: reverse traversal, future-based QK/PV overlap, fragment reductions |
| v3_fa3_overlap.co | Current persistent implementation with host-built task lists and reusable Q storage |
Start with v4 to understand the modern compute loop, then study v3 for task
scheduling. The archive includes all four .co sources, matching generated
CUDA, local harness/configuration files, and executable build/measurement
scripts. The source walkthrough below uses those packaged kernels.
Individual downloads are also available for the
build/measurement runner,
Python baseline harness, and
generated v4 CUDA.
Online softmax: what must remain invariant
For one query tile, keep a running row maximum m, denominator l, and
unnormalized output accumulator O. For each selected KV tile:
S = Q @ K^T
S[i,j] = -inf for masked positions
m_new = max(m, row_max(S))
alpha = exp2((m - m_new) * scale)
P = exp2(S * scale - m_new * scale)
l = alpha * l + row_sum(P)
O = alpha * O + P @ V
m = m_new

After all KV tiles: output = O / l
scale = log2(e) / sqrt(128) = approximately 0.12751743
The source variable logsum holds l, the sum of exponentials; it is not the
logarithm of that sum. QK and PV accumulate in FP32. P is converted to BF16
for the PV tensor-core operation.
Each CTA retains only its tiles and row state, avoiding a global S x S
score/probability matrix. Different query CTAs still load overlapping K/V
tiles, so cache reuse and task order matter. Online softmax also permits
reverse KV traversal, with the usual floating-point rounding differences.
Step 1: establish the sequential baseline
In v1, a CTA owns 128 query rows. Two 128-thread warpgroups each compute 64 rows. Q is copied once; every inner iteration copies K, computes QK and softmax, then copies V and computes PV. These extracts use the surrounding views and accumulators declared in the benchmark kernel:
q_s = dma.copy.swiz<128>
  Q_head.subspan(BLOCK_M, DIM).at(bm, 0) => shared;

// Inside the consumer's KV loop:
acc_s = mma.fill.f32 0.0f;
k_s = dma.copy.swiz<128>
  K_head.subspan(BLOCK_N, DIM).at(bn, 0) => shared;
mma.row.row acc_s, q_s.chunkat(wgm, _), k_s;

// Apply the causal mask and online-softmax update here.

v_s = dma.copy.swiz<128>
  V_head.subspan(BLOCK_N, DIM).at(bn, 0) => shared;
mma.row.col acc_o, acc_s_cast, v_s;
mma.row.row consumes Q and K directly from shared memory for QK. PV uses a
BF16 register fragment (acc_s_cast) and shared V with mma.row.col. There
is no need to manufacture register operands with mma.load for the QK
shared/shared operation.
The dataflow is serial: load K -> QK -> softmax -> load V -> PV. The next
step gives data movement its own execution path.
Step 2: overlap TMA loads with consumers
The v2 experiment uses a 128 x 128 tile, two K stages, two V stages, and three warpgroups: one producer plus two consumers (1p2c). Each consumer still runs QK, softmax, and PV sequentially, while the producer fills future tiles.
Current source should express global-to-shared transfers with tma.load and
bind their completion to an event. This producer extract follows v4 and uses
its names; K/V are traversed from the diagonal toward zero:
shared event qf;
shared event kf[K_STAGES], vf[V_STAGES];
shared event ke[K_STAGES] = ready, ve[V_STAGES] = ready;

// Inside inthreads.async (p == 0):
q_load = tma.load.async.evict_first.swiz<SWIZ>
  Q_head.subspan(BLOCK_M, DIM).at(bm, 0) => q_shared;
trigger qf after q_load;

mutable u32 k_pipe_order = 0;
mutable u32 v_pipe_order = 0;
foreach {issue} in [kv_bound] {
  bn = bm - issue;
  k_slot = k_pipe_order % K_STAGES;
  v_slot = v_pipe_order % V_STAGES;

  wait ke.at(k_pipe_order);
  k_load = tma.load.async.evict_last.swiz<SWIZ>
    K_head.subspan(BLOCK_N, DIM).at(bn, 0) => k_buf[k_slot];
  trigger kf.at(k_pipe_order++) after k_load;

  wait ve.at(v_pipe_order);
  v_load = tma.load.async.evict_last.swiz<SWIZ>
    V_head.subspan(BLOCK_N, DIM).at(bn, 0) => v_buf[v_slot];
  trigger vf.at(v_pipe_order++) after v_load;
}
The two consumers wait for kf/vf, read the shared buffers, and release
ke/ve after the corresponding compute completes. = ready supplies the
initial empty slots. Do not also manually trigger their initial generation.
Three details are essential:
trigger kf.at(order) after k_loadbinds TMA completion without blocking the producer. A plaintriggerimmediately after issuing a load would publish readiness too early.kf.at(order)selects slotorder % K_STAGESand generationorder / K_STAGES. Only data indexing usesk_buf[slot]. Passingorder % K_STAGESto the event loses its generation.- Events express readiness and participation. The compiler selects the hardware barrier and TMA transaction accounting; an event is not a source-level named-barrier ID.
The packaged v2 uses futures and .at(bn), but retains the
tma.copy.async load spelling and explicit initial empty-token triggers.
The ready-initialized, directional form above is the pattern to use in new
code. Shared-to-global output still uses tma.copy.
The packaged v2 stores both consumers' output fragments into a shared output
tile and publishes the complete tile with
tma.copy o_buf => O_head.subspan(BLOCK_M, DIM).at(bm, 0).
This avoids overlapping writes from the older per-consumer TMA output form,
which failed the current correctness check. The measured v2 includes this fix.
Step 3: overlap softmax with PV using operation futures
The current v4 loop makes the dependencies explicit. It has a QK-only prologue, a steady loop that issues QK for the current tile and PV for the previous tile, and a final PV epilogue. There is no dummy zero-probability PV in iteration zero.
Reverse traversal isolates the causal mask
The non-persistent grid launches query tiles in reverse order within each head:
parallel.async {tile, head, batch}
    by [cdiv(Q_SEQ, BLOCK_M), H, B] : block {
  bm = cdiv(Q_SEQ, BLOCK_M) - 1 - tile;
  // The complete kernel declares views, buffers, and thread scopes here.
}
For query tile bm, process KV tiles bm, bm-1, ..., 0. With equal sequence
lengths and BLOCK_M = BLOCK_N = 128, only the first tile intersects the
causal diagonal. Its local mask is:
apply {i, j} in acc_s.span {
  if (j > cid * WG_M + i)
    acc_s.at(i, j) = -inf;
}
The remaining bm iterations need no elementwise causal predicate. Starting
with long query tiles also changes the final grid wave: shorter CTAs are
launched later. That is a scheduling choice to measure, not a guarantee of
CUDA block execution order.
The prologue waits for Q and the first K tile, computes and masks QK, then
initializes the row maximum, denominator, and BF16 probabilities. Only after
this does it initialize acc_o, shortening the accumulator's live range.
The steady-state consumer loop
This is the v4 steady loop. K and V have independent logical orders because QK uses the current K tile while PV still uses the previous V tile:
foreach {step} in [kv_bound - 1] {
  k_slot = k_pipe_order % K_STAGES;
  prev_v_slot = v_pipe_order % V_STAGES;

  acc_s = mma.fill.f32 0.0f;
  wait kf.at(k_pipe_order);
  qk = mma.row.row.async acc_s,
    q_shared.subspan(WG_M, DIM).at(cid, 0), k_buf[k_slot];

  wait vf.at(v_pipe_order);
  pv = mma.row.col.async acc_o, acc_s_cast, v_buf[prev_v_slot];

  wait qk;
  trigger ke.at(k_pipe_order++);

  copy(scores_max_prev, scores_max);
  reduce_max(scores_max, acc_s, 1);
  apply {i} in scores_max.span {
    scores_max.at(i) = __max(scores_max.at(i), scores_max_prev.at(i));
    scores_scale.at(i) = __exp2f(
      scores_max_prev.at(i) * 0.12751743f -
      scores_max.at(i) * 0.12751743f);
  }
  apply {i} in logsum.span
    logsum.at(i) = logsum.at(i) * scores_scale.at(i);
  apply {i, j} in acc_s.span
    acc_s.at(i, j) = __exp2f(
      acc_s.at(i, j) * 0.12751743f - scores_max.at(i) * 0.12751743f);
  apply {i} in scores_sum.span
    scores_sum.at(i) = 0.0f;
  apply {i, j} in acc_s.span
    scores_sum.at(i) = scores_sum.at(i) + acc_s.at(i, j);
  apply {i} in logsum.span
    logsum.at(i) = logsum.at(i) + scores_sum.at(i);

  wait pv;
  trigger ve.at(v_pipe_order++);

  apply {i, j} in acc_s_cast.span
    acc_s_cast.at(i, j) = __to<bf16>(acc_s.at(i, j));
  apply {i, j} in acc_o.span
    acc_o.at(i, j) = acc_o.at(i, j) * scores_scale.at(i);
}
wait qk makes acc_s available while the independent PV operation can
remain in flight. The intervening softmax work uses scalar instructions.
wait pv must precede both rescaling acc_o and overwriting the probability
fragment consumed by PV. The compiler derives WGMMA commit groups and wait
depths from these future dependencies.
Prologue:  QK[0] -> mask + softmax[0] -> P[0]

Steady:    issue QK[n] -> issue PV[n-1] -> wait qk
                                           |
                              softmax[n] while PV may run
                                           |
                              wait pv -> rescale O, write P[n]

Epilogue:  issue PV[last] -> finalize denominator -> wait final_pv -> store
QK and PV are queued tensor-core operations; this schedule does not require them to execute simultaneously on separate tensor cores. The useful overlap is scalar softmax work with an outstanding PV operation. Generated code and profiling determine how much overlap is actually achieved.
Defer the denominator's cross-lane reduction
In v4, apply {i, j} accumulates the score elements owned by each lane into
its local row sum. The running denominator keeps these partial sums through
the KV loop. Because each row's rescaling factor is shared by its lanes, the
cross-lane sum can be deferred until the end:
final_v_slot = v_pipe_order % V_STAGES;
wait vf.at(v_pipe_order);
final_pv = mma.row.col.async acc_o, acc_s_cast, v_buf[final_v_slot];
all_reduce_sum(logsum);
apply {i} in scores_scale.span
  scores_scale.at(i) = 1.0f / logsum.at(i);
wait final_pv;
trigger ve.at(v_pipe_order++);

apply {i, j} in acc_o.span
  acc_o.at(i, j) = acc_o.at(i, j) * scores_scale.at(i);
mma.store acc_o, o_buf.subspan(WG_M, DIM).at(cid, 0);
tma.copy o_buf => O_head.subspan(BLOCK_M, DIM).at(bm, 0);
all_reduce_sum completes and broadcasts the row denominator while final PV
is outstanding. Row maxima still require their reduction on each tile.
Replacing the local sum with reduce_sum would change this schedule.
The persistent v3 implements local/final row sums with two layout-specific CUDA device helpers. The v4 path expresses them with fragment operations. Consequently, claims that the entire current v3 needs no handwritten device code, or that it is only 80 lines including scheduling, are inaccurate.
Step 4: persistent scheduling and cross-task lifetimes
The active v3 launches PERSISTENT_CTAS = 114 CTAs and gives each a list of
query tiles. A tile's causal work grows with bm + 1, so assigning the same
number of tiles to every CTA does not balance work.
The host scheduler uses the following cost estimate:
estimated_cost(bm) = 2 * (bm + 1) + fixed_cost
fixed_cost = 4 by default, configurable with CHOREO_SCHED_FIXED_COST
The factor two accounts for the QK/PV pair. Tasks are considered in descending query-tile order within pairs of batch/head entries and assigned to the currently lightest bin. A pair-preserving rebalance reduces the estimated heavy/light gap, then each bin is stably ordered by batch/head to retain K/V locality. This is a cost-guided static assignment; it is not a device-side work-stealing queue.
The task arrays are cached on the host by workload shape and copied to the device. Warmed kernel timings exclude their one-time construction and upload; report setup cost separately when evaluating changing request shapes.
The Q buffer needs its own handoff
K and V already have empty/full rings, but Q has only one shared slot reused across tasks. Current v3 expresses its lifetime with scalar events:
shared event qf;
shared event qe = ready;

// Producer, once per task:
wait qe;
q_load = tma.load.async.evict_first.swiz<SWIZ>
  Q_head.subspan(BLOCK_M, DIM).at(logical_bm, 0) => q_shared;
trigger qf after q_load;

// Consumers, before the task's first QK:
wait qf;

// Consumers, after the last QK has finished using Q:
trigger qe;
The producer can load the next task's Q while consumers finish final PV and output for the current task. K/V logical orders are initialized outside the task loop and continue across tasks; resetting them would break ring generations. Softmax state and accumulators are initialized anew for each query tile.
The producer's Q-empty wait belongs to the two participating producer warps
(p == 0 && t < 64). Within that scope, warp 0 issues K and warp 1 issues V.
Do not narrow the Q handoff to one lane just because one lane issues TMA:
the compiler uses the actual wait/trigger participants to choose barrier
lowering. The eligible one-slot ready event can lower to a named barrier;
TMA completion and staged rings use their appropriate mbarrier paths.
The current source packs a task as bm | (head << 8) | (batch << 14).
That limits bm to 8 bits and head to 6 bits. Together with the hardcoded
114-CTA grid and equal-length causal assumptions, this makes v3 a tuned
benchmark specialization. Adapting it requires revisiting these limits.
Resources are part of the schedule
At 128 x 128 BF16, Q and O each occupy 32 KiB; two K and two V tiles occupy
128 KiB, for 192 KiB of data buffers per CTA. This explains why adding stages
is a substantial resource change. The current v3/v4 producer requests 40
registers per thread and the consumers request 232 through setreg_dec and
setreg_inc; v2 used 24/240. These are allocation controls, not measured
register counts.
[[launch_bounds(_, 1)]] supplies the minimum-blocks occupancy target used
for compiler register budgeting. It does not enforce a maximum of one CTA per
SM. Actual residency follows from threads, registers, and shared memory.
Likewise, parallel.async expresses an asynchronous launch, not a request
for cluster cooperation or multicast.
Performance measurements
All numbers below were remeasured on September 21, 2026, using the exact downloaded sources. They replace the old measurement tables; no historical timing samples are mixed into this table.
Environment: NVIDIA H800 PCIe (114 SMs), driver 590.48.01, CUDA Toolkit 13.0.88. Main Python environment: PyTorch 2.11.0+cu130, FA3 3.0.0, TileLang 0.1.9, Triton 3.6.0. The WS comparison uses PyTorch 2.10.0+cu128 and Triton 3.8.0+gita59d32fd. Exact dependency revisions and generation flags are in the downloadable manifest.
Each cell reports median milliseconds / TFLOPS. Each implementation has three independently warmed CUDA-event timing rounds per shape, with 50 warmups and 200 launches per round. FA3 is measured at both ends of the suite, so its displayed median combines six samples.
| Implementation | S=4096 ms / TFLOPS | S=8192 ms / TFLOPS | S=16384 ms / TFLOPS |
|---|---|---|---|
| FlashAttention-3 | 1.3944 / 394.3 | 5.3025 / 414.7 | 20.7054 / 424.8 |
| Croqtile v1: sequential | 2.5813 / 213.0 | 9.2858 / 236.8 | 35.3457 / 248.9 |
| Croqtile v2: 1p2c TMA (fixed output) | 1.6600 / 331.2 | 6.1387 / 358.2 | 23.7090 / 371.0 |
| Croqtile v4: non-persistent overlap | 1.4642 / 375.5 | 5.4563 / 403.0 | 21.1821 / 415.3 |
| Croqtile v3: persistent overlap | 1.3967 / 393.6 | 5.2971 / 415.1 | 20.7939 / 423.0 |
| TileLang: 128 x 128, 2 stages | 1.6511 / 333.0 | 6.2546 / 351.6 | 24.2038 / 363.4 |
| Triton 3.6: autotuned, no WS | 1.7542 / 313.4 | 6.6744 / 329.5 | 25.9039 / 339.6 |
| Triton main: Hopper WS, masked loop | 1.9217 / 286.1 | 6.9654 / 315.7 | 26.6264 / 330.4 |
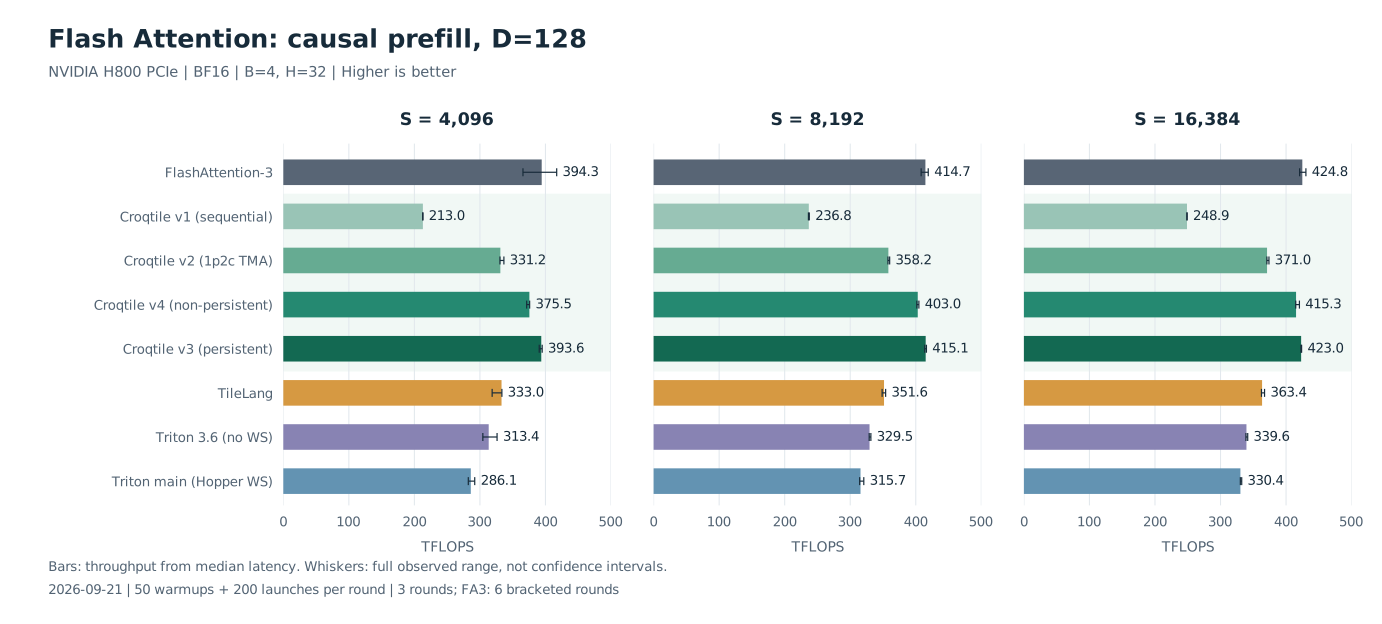
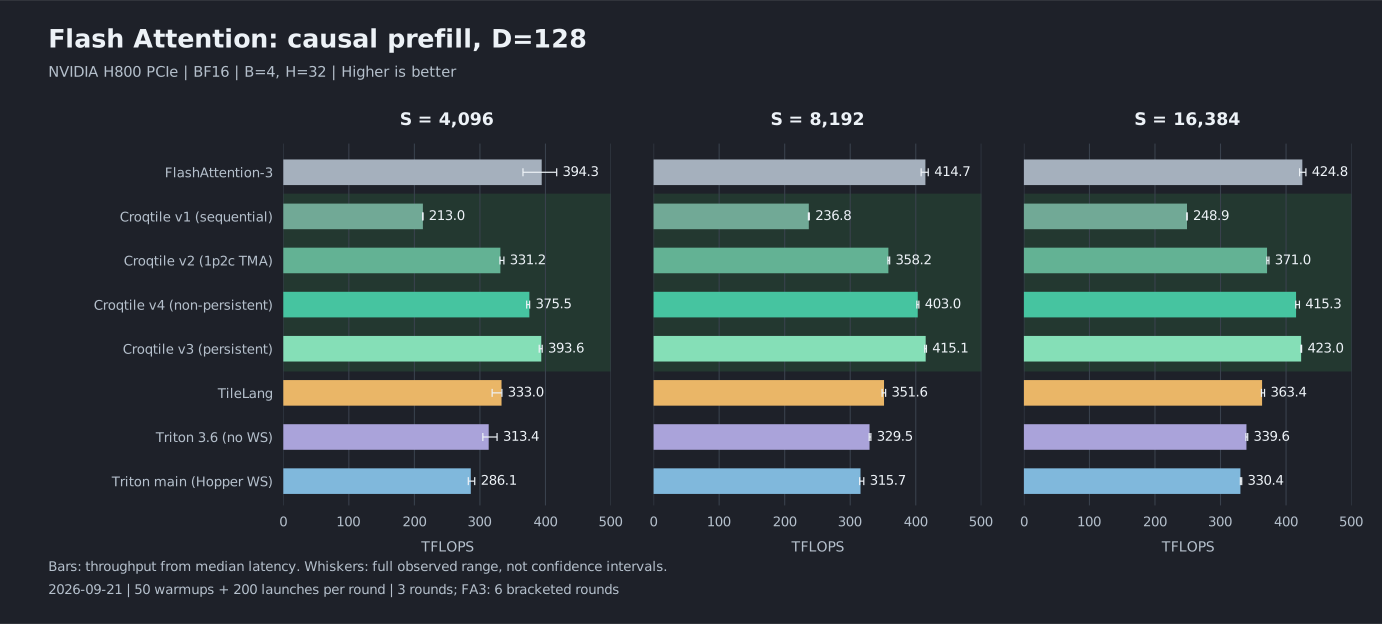
Bars show throughput computed from median latency; whiskers show the full observed range, not confidence intervals. All panels use the same zero-based scale. The figure is generated directly from the measured CSV using the downloadable plot script.
At S=8192, v4 is 1.70x and v3 is 1.75x faster than the sequential v1 in this run. The v3 and FA3 medians are effectively tied at this shape; the measured difference is smaller than the FA3 drift below. This is a comparison of these packaged implementations and configurations, not a claim of each library's best achievable performance.
Timing scope and comparison limits
All inputs and outputs are BF16, with FP32 accumulation and causal masking. The older Triton scripts used FP16; the packaged variants have been converted to BF16 and independently checked. Triton receives contiguous BHSD tensors, with the one-time BSHD/BHSD conversion excluded from timing; the other implementations consume BSHD. Thus layout conversion cost is not compared.
CUDA Graphs are not used. Compilation, autotuning, input preparation, correctness checks, and v3's one-time scheduler setup are outside the timed region. Python output allocations and wrapper launch work remain inside the repeated invocation, so host launch gaps can affect CUDA-event elapsed time. These are warmed invocation measurements, not application end-to-end latency.
The updated Triton+WS kernel uses device tensor descriptors and
tl.range(warp_specialize=True). The old aref launch options are no longer
accepted by the measured compiler. A single masked causal loop avoids that
revision's compiler failure on the old split loops; the wrapper requires
12 emitted warps (384 threads), preventing a silent non-WS fallback. This
row is not a remeasurement of the old aref implementation.
GPU clocks were not locked, and backends ran sequentially. The runner waits for at most 65 C before each backend, but that is not a constant-temperature guarantee during measurement. FA3's first/last three-sample medians show:
| Sequence | FA3 before (ms) | FA3 after (ms) | Change |
|---|---|---|---|
| 4096 | 1.3908 | 1.3980 | +0.52% |
| 8192 | 5.2543 | 5.3796 | +2.39% |
| 16384 | 20.5006 | 20.8591 | +1.75% |
At S=4096, FA3's six samples span 1.3180-1.5034 ms; short-shape results are particularly sensitive to invocation variability. Do not interpret small percentage gaps as definitive wins. Every sample, min/max range, GPU-state observation, and source SHA-256 is retained in results.json and summary.csv. The archives include all raw verification and timing logs.
Throughput counts approximate useful causal QK plus PV work:
TFLOPS = 2 * B * H * S * S * D / (milliseconds * 1e9).
It excludes scalar softmax work and extra diagonal-tile arithmetic.
Correctness gate
All eight implementations passed all three shapes before their timing samples were accepted. Each Choreo check samples 4096 output elements, including targeted tail rows. Python baselines check 261760-262016 output elements per shape against explicit FP32 attention on selected rows across every batch/head, including tile boundaries and sequence tails. TF32 is disabled for that oracle.
Both harnesses use abs(error) <= 0.05 + 0.1 * abs(reference). The largest
observed absolute error was 0.00203 or less for Choreo and 0.00298 or less for
the Python baselines. These are sampled checks, not exhaustive tensor checks.
Each harness uses seed 42, Q/K uniform in [-2,2], and V uniform in [-1,1];
the C++ and PyTorch RNGs do not generate bit-identical inputs.
Download and reproduce
Download the standalone ZIP or tar.gz. Both contain the same sources, scripts, runtime headers, and measured results. The SHA-256 checksums identify the archives. See the package README for dependencies, licensing, and the measurement contract.
tar -xzf flash-attention-standalone.tar.gz
cd flash-attention-standalone
export CUDA_HOME=/usr/local/cuda
export CUTE_HOME=/path/to/cutlass

# Builds the included CUDA and verifies/times all four Choreo kernels.
bash run.sh --gpu 0 --backends v1,v2,v4,v3

# Full comparison, including the separate Triton+WS environment.
bash run.sh --gpu 0 \
  --python /path/to/main-environment/bin/python \
  --ws-python /path/to/triton-ws-environment/bin/python
No Choreo compiler is needed for the default build. To modify a .co kernel
and regenerate its CUDA, use a compatible compiler:
bash run.sh --build-only --regenerate --backends v4 \
  --choreo /path/to/choreo
bash run.sh --skip-build --gpu 0 --backends v4
The default measurement uses 50 warmups, 200 repeats, and three timing rounds
per shape. Set --warmup, --repeat, and --rounds to change that protocol.
Each run creates a new results/<UTC timestamp>/ directory containing raw
logs, results.json, summary.csv, and summary.md. A failed correctness
check or unavailable backend fails the suite and marks the partial result as
incomplete. The scripts never substitute another implementation silently.
Inspect the included CUDA in generated/ for TMA completion binding, WGMMA
issue/wait placement, K/V releases, final denominator reduction, and output
stores. The build writes resource reports to build/*-nvcc.log. To profile
the standalone v4 after building it:
CUDA_VISIBLE_DEVICES=0 MHA_SEQ=8192 CHOREO_DISABLE_TIMING=1 \
  ncu --set full --launch-count 1 \
  -o build/v4-s8192 build/v4
Here MHA_SEQ explicitly selects the workload, and the executable launches
the attention kernel before running its CPU reference check. Always inspect
the captured kernel name and shape.
For further tuning, change one aspect at a time: tile shape, stage count, release placement, cache hints, or task order. Inspect generated code and measure all three shapes before retaining a change. A lower register count, more stages, or a persistent grid is useful only when it improves measured runtime with the required correctness.
Updating older attention code
| Older form or assumption | Current form or interpretation |
|---|---|
Inline event in tma.copy.async<event> |
load = tma.load.async ...; trigger event after load; |
Source-level mma.wait<N> |
op = mma.row.row.async ...; wait op; |
| Event indexed by the physical data slot | event.at(logical_order); data still uses [logical_order % stages] |
| Manually seed an empty ring | Prefer shared event empty[N] = ready; do not seed twice |
| Dummy PV in the first iteration | Separate QK prologue, QK/PV steady loop, final PV |
| Every event is a named barrier | The backend infers the synchronization primitive from participation |
| Persistent scheduling is future work | The active v3 already includes host-built persistent task lists |
The future semantics and event semantics used by these examples are included as downloadable reference snapshots. The source manifest records the generation flags and source versions; measurement records contain SHA-256 hashes of the actual kernels, generated CUDA, and runtime headers. For compiler development and installation, see the open-source Croqtile repository.